Crewline · two71
A process runner for AI agents
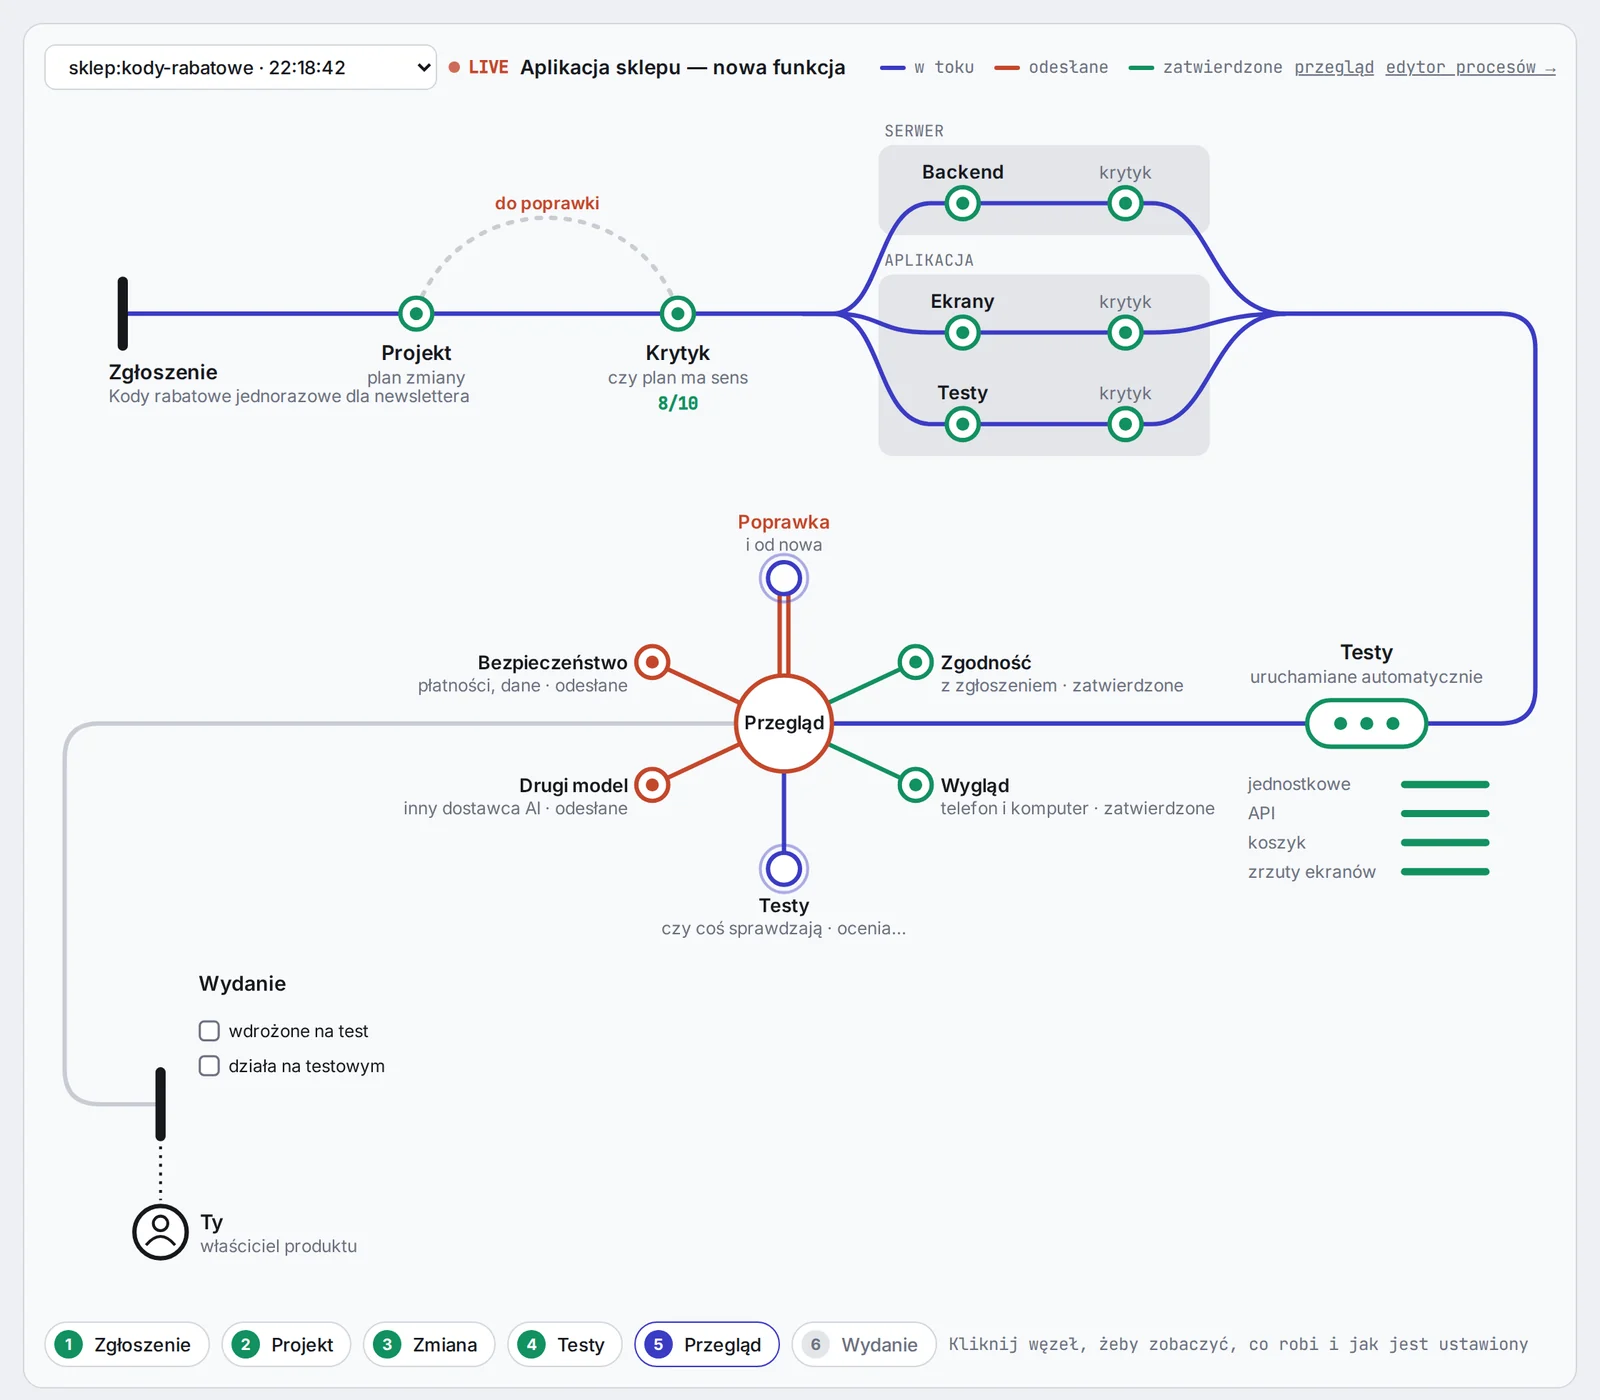
Crewline runs the critic, AI reviewers and tests along your team's process, each with a time and cost limit, and stops where a person decides. The diagram is the execution trace: who worked, what came back for a fix and why.
- in progress or waiting for you
- sent back, with a reason
- approved, with evidence

What Crewline does
The agent's session writes the code and content. Crewline runs the review and check stages.
Runs the reviewers
The critic, reviewers, tests and a second AI model start with one command, in parallel. A reviewer reads only by default and returns a verdict in a fixed JSON format.
Green only with evidence
Tests, API requests and screenshots run once before the review, and every reviewer gets the results. A bad format, no answer or a hit limit means a send-back with a reason.
Cost and time limits
Each reviewer has a cost and time limit, and a review round has a total limit and a maximum number of rounds. Token usage is shown per event, stage and task.
Waits for your decision
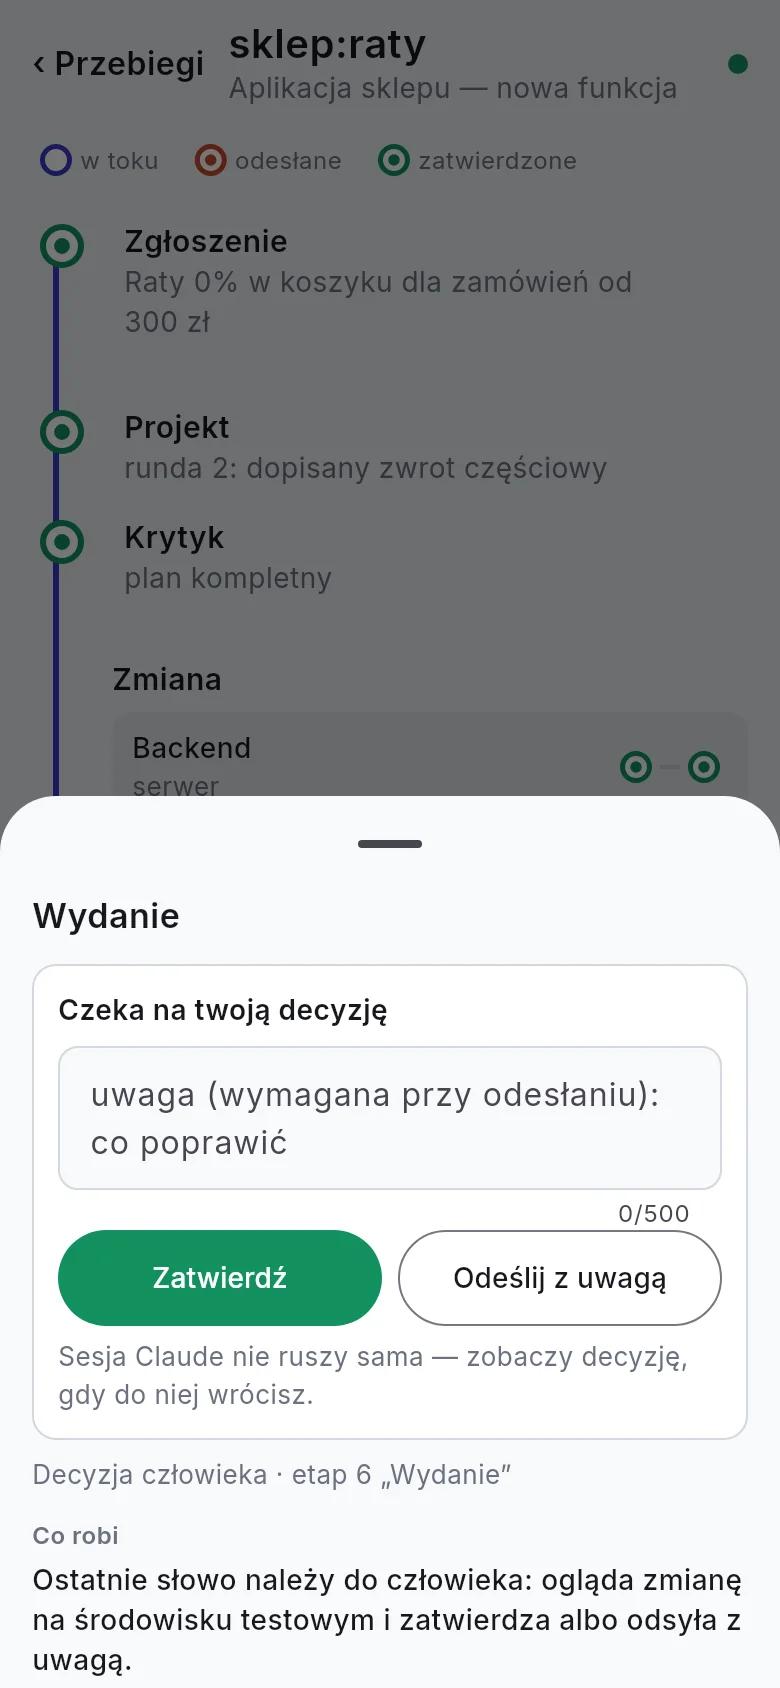
The “You” step waits for “Approve” or “Send back with a note”, on the page or on your phone. The agent's session gets the decision and the note at its next step.
$ pipectl.py run shop review
 ✓ evidence tests  ok
 ✓ evidence api    ok
round 1 of 3 · limit ≈ $3.00
 ✓ r_fit     approved   $0.17  14 s
 ✓ r_sec     approved   $0.21  22 s
 ✗ r_layout  sent_back  $0.19  18 s
   instalment button cut at 360 px
 ✓ r_tests   approved   $0.18  16 s
 ✓ r_second  approved   other  41 s
total 267k tokens · ≈$0.75
1 to fix → exit 1
Sample output in the tool's format, made-up data. The agent's session gets this summary, and the diagram steps light up from the results.
An example to click through
An online shop's team adds instalments to the cart. Replay the run, click a step, then decide.
Events
Waiting for your decision
Check the instalment checkout on staging.
The example runs in your browser, with no server.
Fewer tokens per task
A sample task in our process: two critic rounds and two review rounds of five reviewers each. Crewline runs the reviewers instead of the agent's session, on a cheaper model, with the code diff given right in the prompt.
The number of turns is an estimate. Part of the saving is narrower checking: the old reviewers ran tests and screenshots themselves. These now run once before the review as shared evidence, and with that we estimate about −50%.
Screens
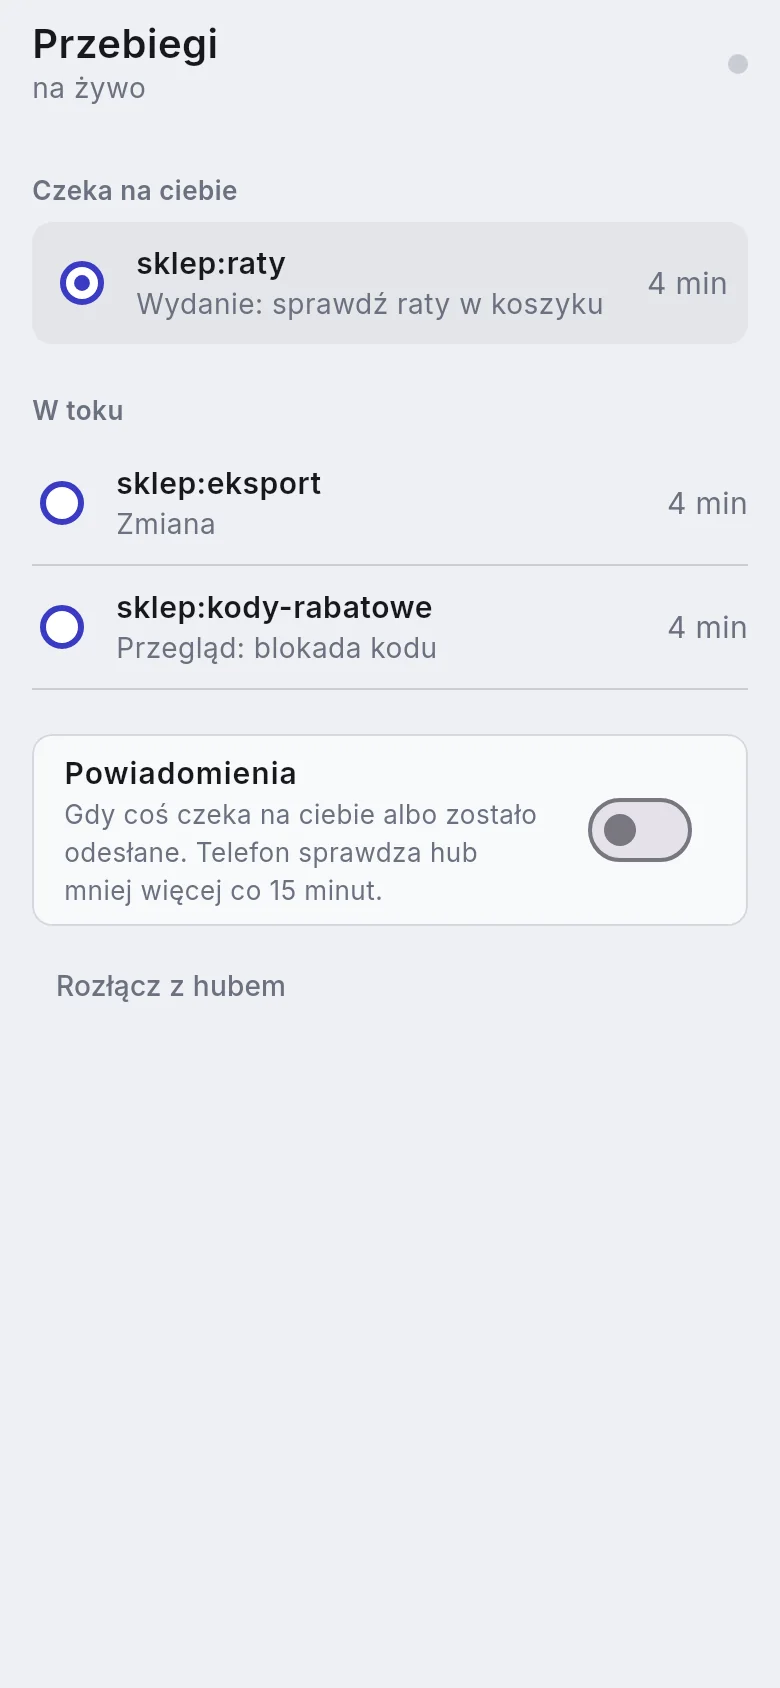
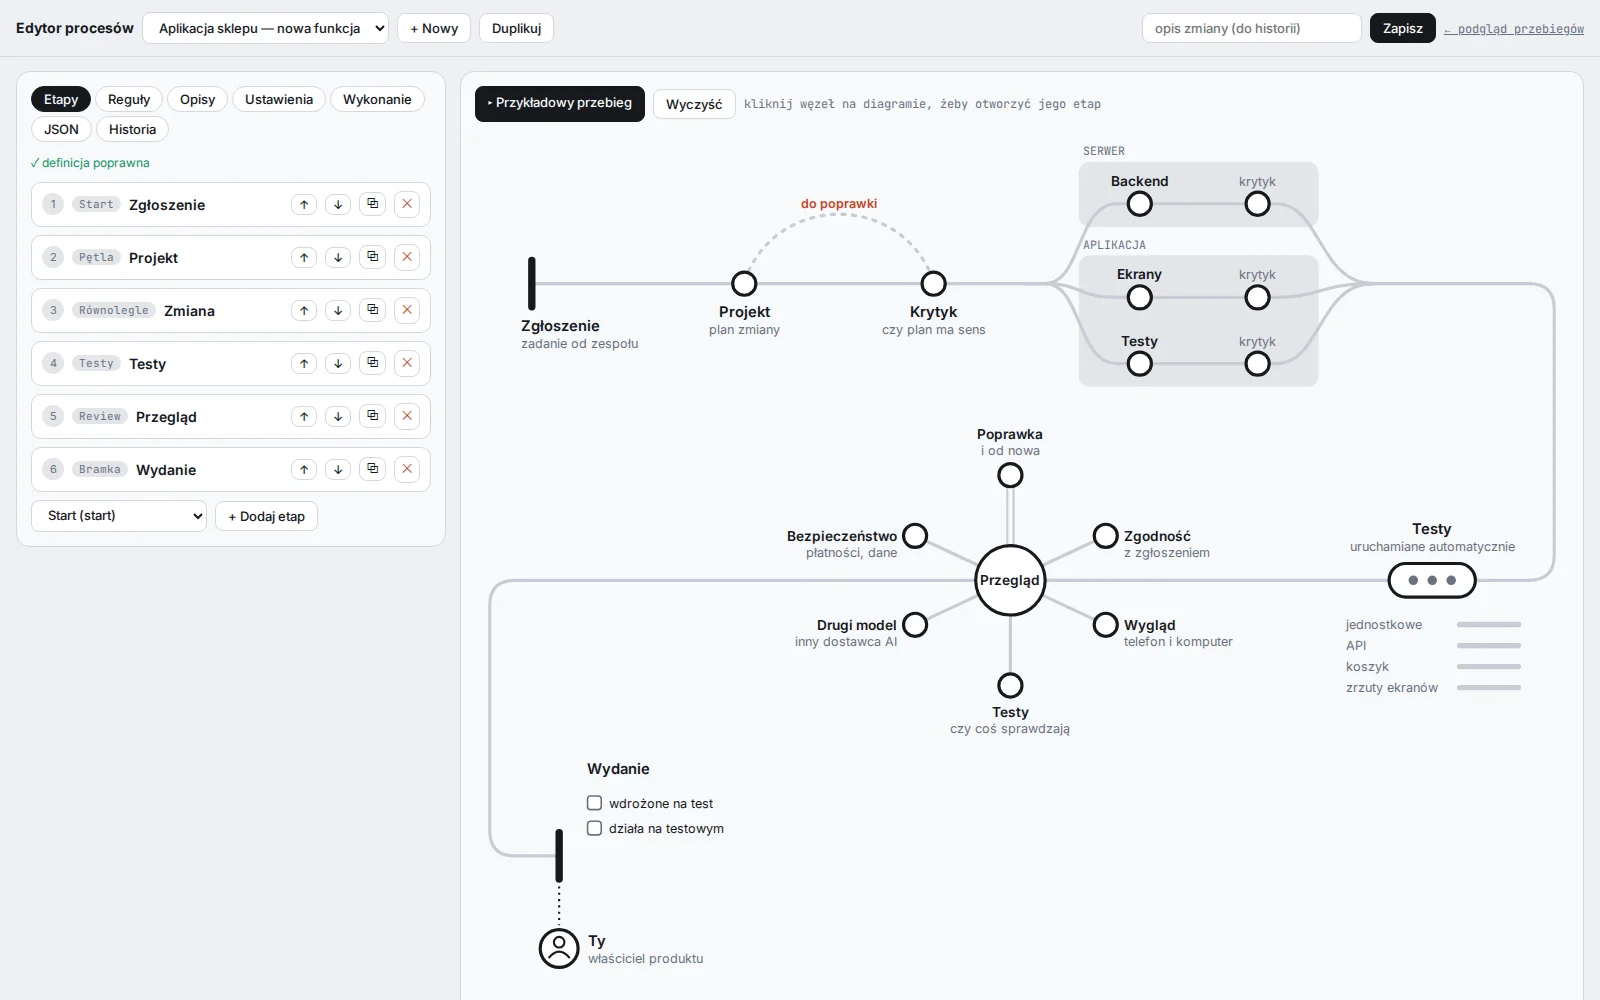
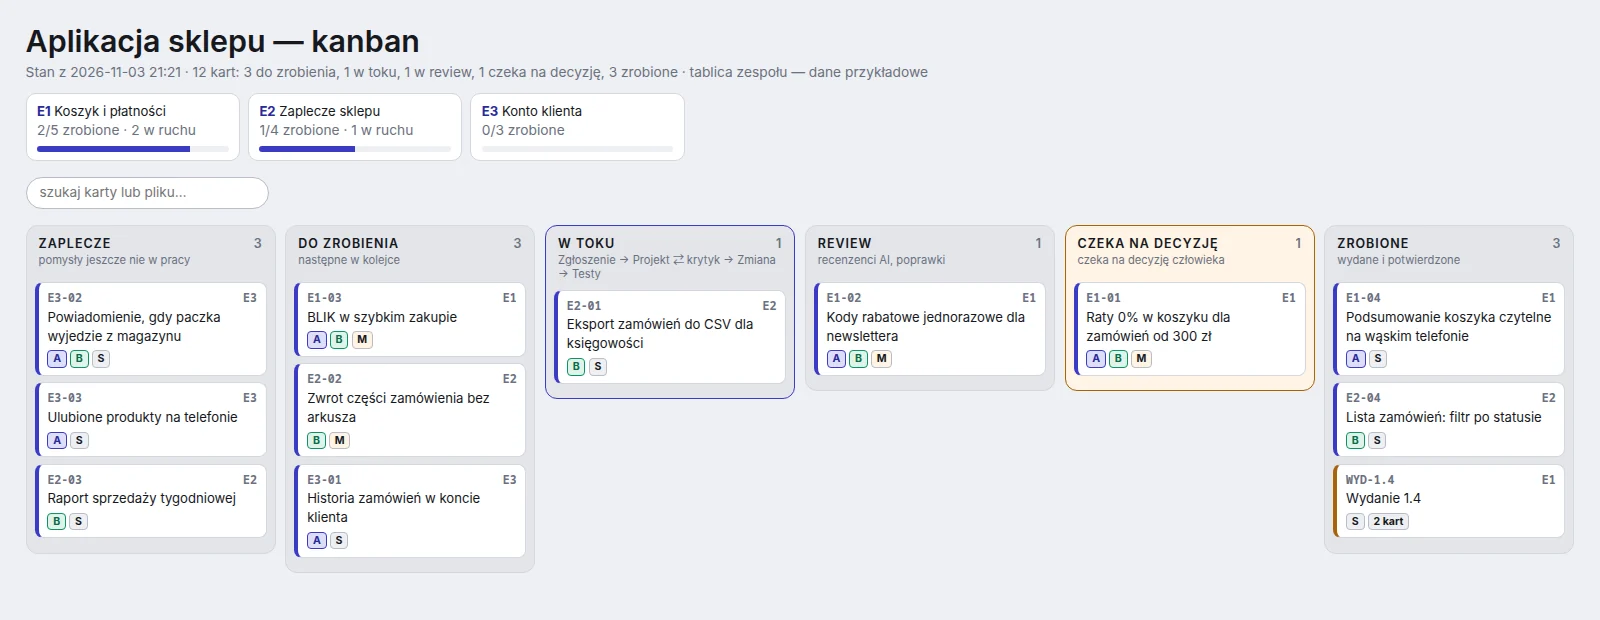
The working tool on a sample shop process. The interface is in Polish.
Also included
- Process editor.Stages from blocks, rules that light up steps, a change history. A definition with errors can't be saved.
- AI proposes, a person accepts.An agent can propose a process change based on run statistics. The proposal waits in the editor.
- Task board.Kanban cards are linked to runs. Moving a card reports a process step.
- Android app.A “waiting for you” list, each run step by step, notifications for decision requests and send-backs.
- Data stays with the team.Execution always happens on the team's computer. A process marked as local never goes online.
In progress: running a whole task from request to release, including the authoring steps.
A rollout at your company
Crewline runs our own day-to-day work with agents. We'll help you describe your process and set the cost limits and the points where a person decides.
Get in touch